The headline
OpenAI leads (90.7/100), followed by Gemini (86.4), Claude (85.9), and Perplexity (80.4). But no single provider wins everything — rankings shift by task type, and even the best model fails badly 8% of the time.
 Request a demo
We tested 4 leading LLMs (Claude, GPT, Gemini, Perplexity) on 345 real-world local search prompts – finding restaurants, checking hours, planning routes, booking tables – each run with and without web search (2,415 evaluations). Every recommended place was verified against Google Search and Maps.
Get the report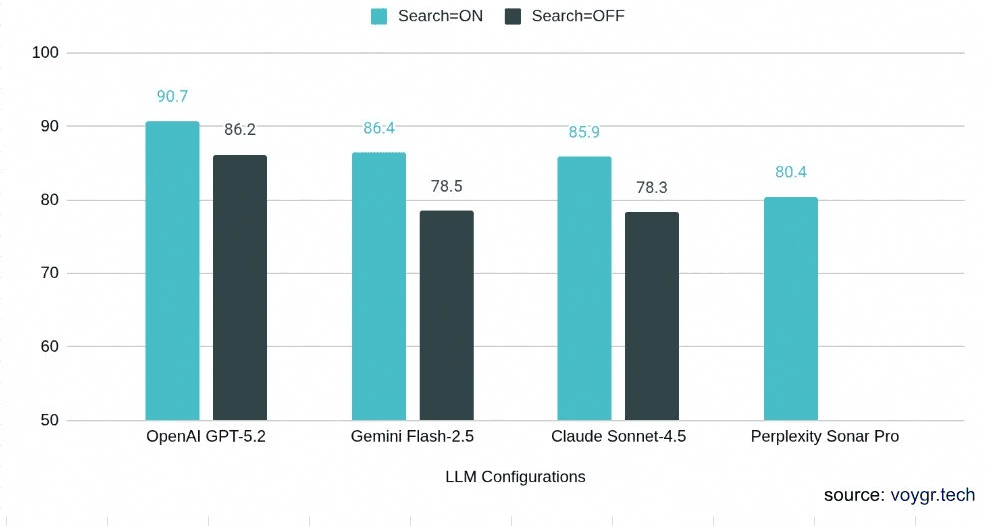
OpenAI leads (90.7/100), followed by Gemini (86.4), Claude (85.9), and Perplexity (80.4). But no single provider wins everything — rankings shift by task type, and even the best model fails badly 8% of the time.
Without search, 1 in 5 places Claude recommends doesn't exist, is permanently closed, or is in the wrong location. Even with search, no provider reliably detects closed venues — all 7 configs confidently gave booking guidance to a shuttered Buenos Aires restaurant.
Web search helps on factual lookups (+8 points) but hurts on transactional tasks — Claude and Gemini both lose 5+ points on booking prompts when search is enabled. Search returns facts about a place instead of guidance on how to act.
Constraint fidelity — whether the recommendations actually match what you asked for — varies 16 points across providers. All models find real places; not all find the right places.
Out of 100, every recommended place verified against Google Search and Maps. The full report breaks this down by task category, region and failure type.
| Provider | Model | Score | Completeness | Accuracy | Constraint match | Plausibility |
|---|---|---|---|---|---|---|
| OpenAI | gpt-5.2 | 90.7 | 100% | 92% | 85% | 91% |
| Gemini | gemini-2.5-flash | 86.4 | 91% | 92% | 77% | 76% |
| Claude | claude-sonnet-4-5 | 85.9 | 99% | 89% | 76% | 79% |
| Perplexity | sonar-pro | 80.4 | 97% | 86% | 69% | 71% |
With web search enabled, OpenAI (gpt-5.2) scored highest at 90.7/100, ahead of Gemini (86.4), Claude (85.9) and Perplexity (80.4). No provider wins every task type: rankings shift between finding places, checking details, planning routes and contacting a business.
Even the best configuration recommended a place that was fabricated, permanently closed or in the wrong neighbourhood about 8% of the time. Without web search, roughly 1 in 5 places Claude recommended had such a fatal flaw. No provider reliably detected that a venue had closed.
It helps discovery (+10 to +21 points) but hurts transactional tasks such as booking a table: Claude and Gemini both lost more than 5 points on those prompts with search on. Search returns facts about a place instead of guidance on how to act.